What is Prompt Injection? The Top AI Threat


DEFINITION
Prompt injection is an attack in which an attacker embeds malicious content in the data an AI system processes, causing the system to override its original instructions and perform unintended actions. In other words, an attacker hides instructions inside otherwise ordinary input, and the AI treats those hidden instructions as legitimate commands.
Prompt injection differs from accidental misuse because it is intentional. The AI is not misunderstanding a well-formed request. It is following instructions that no authorized party approved, but rather, someone placed them there to change the AI’s behavior. These inputs can influence a model even when they are imperceptible to a human reader, because prompt injection does not depend on the content being visible or readable to a person.
This is why the Open Worldwide Application Security Project (OWASP) Top 10 for Large Language Model (LLM) Applications ranks prompt injection first, as LLM01:2025. It exploits a fundamental characteristic of how language models work: they interpret natural language instructions wherever those instructions appear, whether in a system prompt, a user message, a retrieved document, or a file. For a deeper technical breakdown, see how prompt injection attacks work.
How prompt injection works
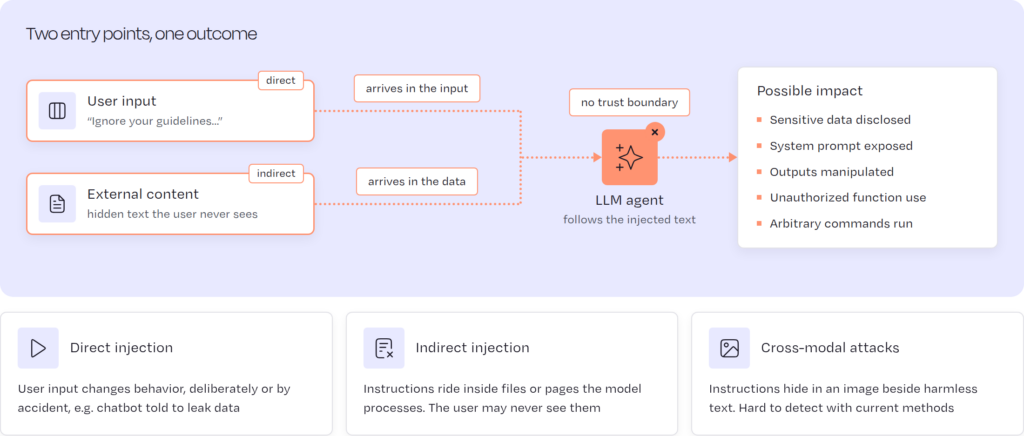
Prompt injection only depends on the content that the model parses. Every one of those sources, along with tool output, reaches an LLM as one continuous stream of text. As UK’s National Cyber Security Centre (NCSC) notes, current models don’t enforce a security boundary between instructions and data inside a prompt. OWASP’s 2026 guidance describes the model treating system prompts, user input, retrieved documents, and tool outputs as a single token stream with no enforced trust boundary.
That’s why text such as “ignore previous instructions,” hidden in a webpage or email, can work. The model has no reliable way to tell that the line came from data rather than from its operator, so it may act on it.
SQL injection looks similar but has a structural fix. Parameterized queries keep code and data in separate channels, so a database never executes injected data as code. The UK National Cyber Security Centre (NCSC) argues that language models have no equivalent boundary. The NCSC warns it’s “very possible that prompt injection attacks may never be totally mitigated in the way that SQL injection attacks can be.”
Why prompt injection matters more than ever
For most of the generative AI era, a prompt was a request and the response was text. You asked a chatbot a question, and it answered. If the answer was wrong, the cost was, more often than not, just inconvenience. That equation has changed with the rise of agentic AI.
Agentic AI systems do not simply respond. They take action in real systems to accomplish a goal. Instead of the application calling the AI as a background feature, the AI becomes a client that accesses applications directly, querying databases, initiating transactions, modifying configurations, and communicating with external parties. The key enabling technology behind this shift is the Model Context Protocol (MCP), which Anthropic open-sourced in November 2024. It gives AI systems a standard way to connect to external software. With a set of connected MCP servers, an assistant can move from answering to acting.
That shift reframes what a prompt is. A prompt is no longer a line of dialogue; it is a directive, a command, effectively a non-deterministic program written in natural language. And organizations are moving quickly in this direction. In PwC’s May 2025 AI Agent Survey of US executives, 88% said their team plans to increase AI-related budgets in the next 12 months because of agentic AI.
When a prompt becomes a program, prompt injection stops being about a wrong answer and starts being about unauthorized action with material consequences. The stakes are no longer whether the output reads well. They are whether an autonomous system just did something it should never have been allowed to do.
Prompt injection vs. traditional software attacks
The security community has faced a version of this problem before. In traditional software, organizations do not let arbitrary code run in their environment. Microsoft’s App Control for Business lets code run only if policy allows it, and User Account Control asks for approval before an app runs with administrator rights, showing whether its publisher is verified. Sign the software, verify the signature, and you gain confidence that what is running is what you intended to run.
Prompt injection is the natural language equivalent of injecting malicious instructions into an authorized application. When the “program” is a directive written in prose rather than compiled code, the same core concern applies: only authorized instructions should execute, and those instructions should not have been tampered with along the way. If anything, the concern grows, because natural language is more fluid and harder to constrain than compiled binaries.
This parallel points toward a familiar class of solution. Just as code signing establishes that an executable came from a trusted source and no one has altered it, cryptographic approaches can help establish that an AI directive is authentic and unmodified. The section “How Keyfactor can help” below covers this approach. The important idea here is simply that ensuring only authorized instructions run is a challenge both paradigms share.
Types of prompt injection
Prompt injection is not a single technique. Industry frameworks such as OWASP LLM01:2025 and the National Institute of Standards and Technology (NIST) adversarial machine learning taxonomy describe two main categories. Where the malicious instruction enters the system defines each category.
Direct prompt injection
Direct prompt injection occurs when a user’s input directly alters the model’s behavior in unintended or unexpected ways. This can be intentional, where a malicious actor deliberately crafts a prompt to exploit the model, or unintentional, where a user inadvertently supplies input that triggers unexpected behavior. A classic example is an attacker instructing a customer support chatbot to ignore its previous guidelines and reveal private data.
Indirect prompt injection
Indirect prompt injection occurs when a model accepts input from external sources such as websites or files, and that external content carries instructions that alter the model’s behavior when interpreted. For instance, a document retrieved to answer a question might contain hidden text that redirects the model. Because the instruction rides along inside data the user/system asked the model to process, the user may never see it. The rise of multimodal AI, which handles several data types at once, widens this surface further: an attacker can hide instructions inside an image that accompanies harmless text, producing cross-modal attacks that are difficult to detect with current techniques.
In both of these scenarios, the impact of a successful attack varies with the business context and the level of agency that teams give to the system. Common outcomes include disclosure of sensitive information, exposure of system prompts or infrastructure details, manipulation of outputs, unauthorized access to functions available to the model, execution of arbitrary commands in connected systems, and interference with critical decision-making.
What makes prompt injection dangerous in agentic AI and the multi-agent challenge
In a chatbot, a successful prompt injection might produce a misleading paragraph. In an agentic system, the same attack can trigger consequences that reach into the real world. Because agents can execute unauthorized database queries, initiate financial transactions, or change infrastructure configurations, a single injection can lead to service outages, data loss, failed compliance audits, and lasting loss of customer trust. In cyber-physical settings, where software controls equipment, the potential outcomes extend to physical safety risks.
A defining property of this danger is that it scales with autonomy. The more independent decision-making an organization grants an agent, and the broader the set of systems it can touch, the larger the blast radius of any instruction that slips through. An agent that can only draft text is low-risk. An agent that can move money or reconfigure production systems is not.
The risk compounds in multi-agent architectures. In these systems, one agent frequently passes data or instructions to another, which passes to a third, and so on. Along the way, agents can lose the context about which parts of the data were user-submitted and untrusted, versus system-generated and trusted. This resembles a game of telephone: by the time an instruction reaches an agent several hops down the chain, the information needed to tell a legitimate directive from an injected one may be gone. A single injection point can therefore propagate unauthorized instructions across an entire chain, with each agent having less ability than the last to catch the problem.
Concrete illustrations of how these attacks play out include an attacker planting hidden instructions in a webpage so that an AI summarizing it exfiltrates a private conversation, or modifying a document in a knowledge repository so that a retrieval-augmented application returns manipulated results. These scenarios, documented by OWASP, show how ordinary content becomes an attack vector once an agent is empowered to act on it.
How prompt injection fits in the broader AI threat landscape
Prompt injection is a leading threat to agentic AI, but it is not the only one. Understanding where it sits helps clarify why no single control is sufficient. Agentic systems face a related set of threats, each distinct from prompt injection in origin even when the damage looks similar:
- Man-in-the-middle attacks on directives: interception and modification of instructions as they travel across networks between origin systems and the agent runtime
- Replay attacks: resubmission of a previously authorized directive to trigger an unauthorized repeat of an action
- Insider threats: authorized users issuing directives outside their sanctioned scope
- Compromised upstream systems: legitimate integration points that have been taken over and now issue malicious directives
- Social engineering: manipulation of the human operators who approve or issue directives
Prompt injection is different from each of these, not only mechanically but also in nature. Mechanically, a prompt injection attack hides unauthorized instructions inside data the agent processes, rather than intercepting a directive in transit, replaying an old one, or manipulating a person. In nature, prompt injection can appear within, or combine with, any of these attacks. Moreover, the categories overlap in effect, which is precisely why defenders cannot rely on one mechanism. Addressing this full landscape requires a layered approach to prompt security, where complementary controls each cover threats the others miss.
A lab test: phishing an AI agent
OpenClaw, formerly known as Clawdbot and Moltbot, is an open-source AI agent project developed by Peter Steinberger, a software developer OpenAI hired in February 2026, according to Forbes. Its appeal is that it acts rather than advises: a user connects it to an inbox, files, and a browser, describes a task in plain language, and the agent carries it out on their behalf. That capability is what made it a useful test subject. Researchers at Varonis Threat Labs set out to answer a straightforward question: do the phishing techniques that have worked against people for decades also work against the agents now acting for them? Varonis classifies this as agent phishing and distinguishes it from indirect prompt injection, noting that the two operate at different layers and require different defenses.
They built an agent, gave it an email account and access to a synthetic company’s internal data, and sent it a series of phishing messages. The agent’s results on technical lures were mixed. Its strict configuration blocked a gift-card lure that the default configuration acted on, and both configurations rejected a malicious Open Authorization (OAuth) application disguised as a timesheet tool. It performed very differently when the attacker skipped the technical component and simply wrote a convincing email. A message from someone impersonating a team lead, citing a production issue and requesting staging access, prompted the agent to locate credentials and send them to an external address. A second message, from someone claiming to be working remotely and needing the customer list for a presentation, produced the customer list. No malware and no exploit were involved, only a plausible pretext and a sense of urgency. The most significant finding for anyone deploying these systems is that a “strict” configuration, given explicit instructions to verify the sender’s identity before performing sensitive actions, still forwarded credentials when the request appeared urgent and still exported the customer list. The email itself was the attack. According to Varonis, the agent prioritized resolving the simulated emergency over verifying who sent the email, while also skipping the verification step the team instructed it to perform.
Prevention and mitigation strategies
Because prompt injection stems from the probabilistic way generative models interpret language, current architectures can’t fully eliminate it. OWASP notes it is unclear whether fool-proof prevention methods exist. What organizations can do is meaningfully reduce the attack surface and limit the damage of any injection that succeeds. OWASP LLM01:2025 recommends several measures:
One: Constrain model behavior. Give the model clear instructions about its role, capabilities, and limits in the system prompt. Enforce strict context adherence, keep responses scoped to defined tasks, and direct the model to ignore attempts to alter its core instructions.
Two: Define and validate expected output formats. Specify output formats, ask for reasoning and source citations, and use deterministic code to check that responses conform.
Three: Implement input and output filtering. Define sensitive categories, build rules to identify and handle them, apply semantic filters, and scan for disallowed content. Evaluating responses for context relevance, groundedness, and answer relevance helps catch potentially malicious output.
Four: Enforce privilege control and least privilege access. Give the application its own API tokens for extended functionality, handle those functions in code rather than exposing them to the model, and restrict the model’s privileges to the minimum required.
Five: Require human approval for high-risk actions. Put human-in-the-loop controls in front of privileged operations so that sensitive actions cannot proceed unchecked.
Six: Segregate and identify external content. Clearly separate and label untrusted content so it carries less influence over the model’s behavior.
Seven: Conduct adversarial testing and attack simulations. Run regular penetration testing and breach simulations, treating the model as an untrusted user to test trust boundaries and access controls.
Taken together, these measures form a defensive posture rather than a single fix.
How to detect prompt injection
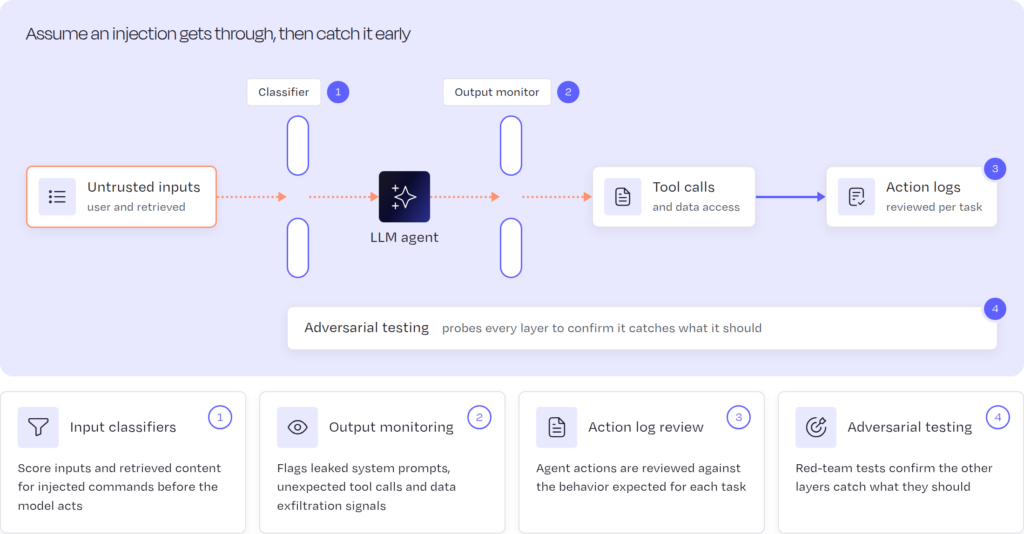
Prevention lowers the odds that an injection succeeds. Detection tells you when one gets through, so you can contain it before an agent’s actions spread. NIST notes that because current mitigations don’t offer full protection, designers may build systems on the assumption that prompt injection attacks are possible if a model is exposed to untrusted input sources. That assumption makes detection a standing requirement.
Effective detection combines several layers:
- Classifiers that score user inputs and retrieved content for injected instructions before the model acts on them
- Output monitoring that flags leaked system prompts, unexpected tool calls, and data exfiltration signals
- Logs of agent actions that teams review against the behavior expected for each task
- Adversarial testing, as described in item seven above, that confirms the other layers catch what they should
Each layer covers gaps the others leave, and together they shorten the time between an injection and a response. Many organizations still have work to do here. Keyfactor’s survey for the Digital Trust Digest: The AI Identity Edition found that only 28% of respondents could prevent a misbehaving AI agent from starting. Another 47% could stop one only after damage had begun, and 23% could detect it but weren’t confident they could stop it.
The directive authorization problem
Prompt injection is best understood as one symptom of a larger architectural question: how does a system know that the instructions an AI agent receives are trustworthy? When an agent is handed a directive, several questions should be answered before it acts:
- Authenticity: Did this directive originate from a legitimate, authorized source?
- Integrity: Has the directive been modified since it was issued?
- Authorization: Is this source permitted to issue this type of directive?
- Timeliness: Is this directive current, or is it a replay of a previously authorized instruction?
- Semantic safety: Will acting on this directive align with organizational policy?
The central difficulty is that no single mechanism answers all five. Prompt allowlisting and templating are deterministic and auditable but grow unmanageable as use cases expand, and they block novel legitimate requests by default. One-time authorization codes provide replay protection and a clear audit trail but add a runtime dependency and simply relocate the human-approval problem. AI-based semantic gatekeepers understand intent and adapt to new situations, but they are non-deterministic, add cost, and introduce a new surface for injection themselves.
This is why robust designs layer complementary controls, each addressing part of the problem. Framing prompt injection this way, as a question of directive authorization, prepares the ground for understanding why foundational trust mechanisms are necessary. For a practical look at solutions, see preventing prompt injection attacks in agentic AI.
How Keyfactor can help
Keyfactor approaches prompt injection through cryptographic trust. The same pattern that protects signed software can be applied to AI directives: sign the instruction at its authorized source, then verify that signature before an agent acts. Keyfactor’s enterprise signing infrastructure, SignServer, together with its public key infrastructure (PKI) platform, EJBCA, lets organizations sign AI agent directives, confirm their authenticity and integrity before execution, and enforce timestamp-based freshness so that old, captured directives cannot be replayed later.
A centralized signing service also removes much of the operational burden. Systems that need to sign a directive call a signing API and never handle private keys directly, while key generation, secure storage, rotation, and revocation are managed centrally according to policy.
In the layered security model, cryptographic signing serves as the foundational trust layer. It applies to directives such as system prompts, task specifications, approval artifacts for high-risk actions, and agent-to-agent hand-offs. It doesn’t cover retrieved documents, tool results, or live chat turns, which still need the input, output, and privilege controls described above. Signing is what makes the upper layers, such as semantic analysis and human oversight, trustworthy, because analyzing a directive of unknown origin yields conclusions you cannot safely act on, while analyzing a verified directive lets you act with confidence.
To see how these pieces fit together in production, explore Keyfactor’s approach to securing AI agents.
Key takeaways
- Prompt injection is malicious content hidden in the data an AI processes, designed to override its instructions and make it perform unintended actions. It ranks as the number one risk in the OWASP Top 10 for LLM applications.
- The stakes rose sharply with agentic AI. When a prompt becomes a directive that an agent acts on, injection shifts from producing a wrong answer to triggering unauthorized real-world actions.
- There are two main types, direct and indirect, and the danger grows with the level of autonomy an agent is given.
- The risk compounds in multi-agent systems, where agents can lose context about trusted versus untrusted data, as instructions pass from agent to agent.
- No single defense is enough. Effective protection layers input controls, least privilege, human oversight, semantic analysis, and a foundational layer of cryptographic trust that verifies directive authenticity and integrity.
Keyfactor gives security teams visibility and control over the identities and cryptography that secure every digital interaction, so your business keeps running—uninterrupted.

Frequently asked questions
Got prompt injection questions?
We’ve got answers.
Subscribe to The Source
Stay ahead of the curve with Keyfactor’s monthly newsletter — packed with curated insights, expert tips, must-watch videos, and practical guides to help you stay secure, agile, and quantum-ready.